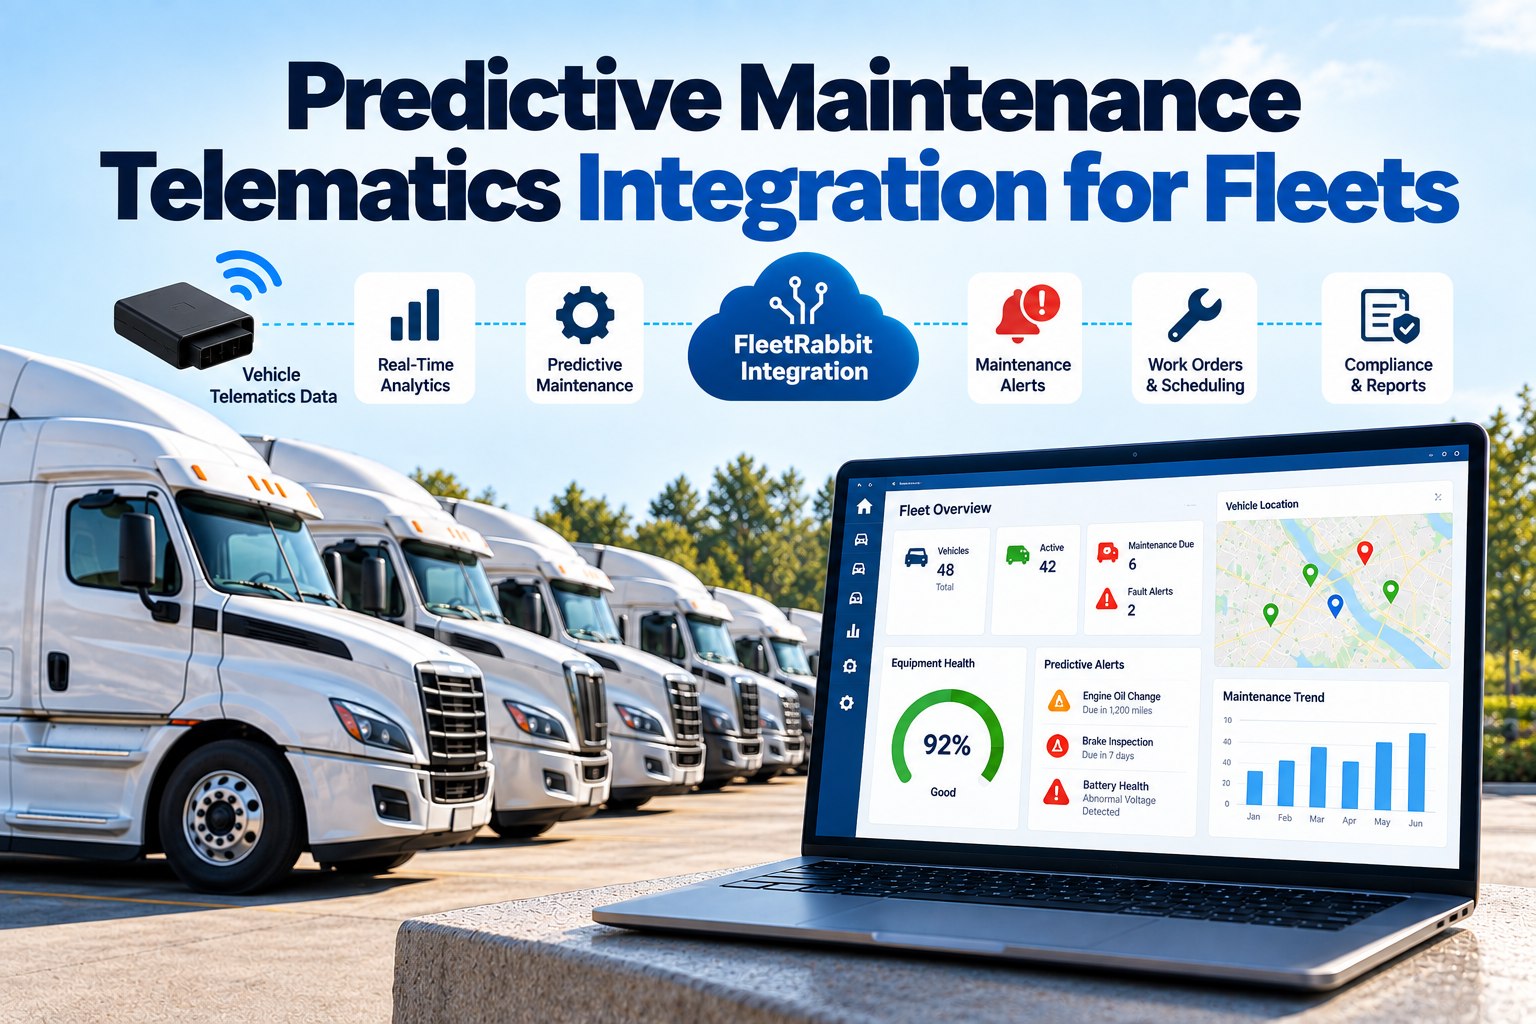
If you have decided to do this, the first real decision is not which vendor. It is which components, and the honest answer is far fewer than a vendor will suggest. Two pieces of established reliability engineering govern the whole programme. The first is the P-F interval: the time between when a failure-in-the-making can be identified, the potential failure or P, and the actual failed state where acceptable performance standards are no longer sustained, the functional failure or F. Your monitoring has to be frequent enough to land inside that window, and conventional practice is to set the task at one-half the P-F interval. The second is older and more uncomfortable. The United Airlines studies that produced reliability-centred maintenance in the 1960s found that only three of six observed failure patterns are age-related at all — the rest show no relationship between age and failure rate, which is why scheduled overhaul and replacement at a fixed frequency turns out to be effective in a small minority of cases. Those two facts together tell you exactly what a predictive programme should target and what it should leave alone. This page is the implementation side: screening components through four gates, calculating the monitoring interval, designing a pilot with kill criteria, and the seven numbers that tell you whether it worked. If you are still deciding whether telematics data can support any of this, the capability side is covered separately. Scope a pilot with us, or spin up a workspace first.
The Hard Part Is Not the Model. It Is Deciding What Deserves Watching.
For maintenance managers and reliability leads who have already decided to build a predictive programme: component screening, the P-F interval arithmetic that sets your monitoring frequency, a pilot design with explicit kill criteria, and the metrics that prove it.
No credit card required. Signals, inspections and work orders against one unit record.
The Interval That Decides Everything
Every condition-based task in your programme is really one number: how long you have between the first detectable sign and the point the component stops doing its job. Get that number and the monitoring frequency follows. Guess it and you are monitoring for reassurance. We will work out the intervals for your components.
Curve is illustrative. The P-F interval is defined as the time interval between when a failure-in-the-making can be identified and the actual failed state where acceptable performance standards are no longer sustained. Setting the task at one-half the interval is the conventional rule, and it rests on an assumption worth stating out loud — that inspections are nearly 100 percent effective at detecting the potential failure. Where detection is less reliable than that, or the consequence is safety-critical, the interval has to come in further.
If you space inspections so that exactly two fit inside one P-F interval, the effective margin approaches zero — because the second inspection can land almost at F, leaving no time to get the part, book the bay and do the work. The number you actually need is the net P-F interval: the detection window minus the time it takes you to act on what you found. A fleet with a two-week parts lead time and a three-week P-F interval does not have a predictive opportunity. It has a warning.
Why Calendar Replacement Mostly Does Not Work
This is the finding that created condition-based maintenance as a discipline, and it is still the strongest argument for the programme you are building. Start recording the history that makes this measurable for your own fleet.
Patterns and shares as commonly cited from the United Airlines reliability studies of the 1960s, conducted under FAA guidance, which became the basis of reliability-centred maintenance. Treat the individual percentages as indicative rather than exact — they are quoted with small variations across retellings and do not always sum cleanly — but the structural finding is robust and is what matters here: only the three age-related patterns give scheduled replacement anything to work with, and they are a small minority of observed failures. For the large remainder, replacing a component because it has reached a certain age accomplishes nothing, and may introduce infant-mortality failures that would not otherwise have happened.
Bring Three Components You Are Considering
In half an hour we will run them through the four gates with you, estimate the P-F interval for each from your own failure history, and tell you honestly which ones are worth monitoring and which should be run to failure. You will leave with a shortlist and a pilot scope, whether or not you use our software for it.
Four Gates Every Candidate Has to Pass
Run each component you are considering through these in order. Most drop out at gate one or gate three, and that is the point — a short list you can actually deliver beats a dashboard covering everything and predicting nothing.
A component that fails randomly has no P and therefore no warning to detect. Bearings, brake linings, belts, hoses and aftertreatment degrade. Sensors, relays, connectors and control modules mostly do not.
Not a signal that exists in principle — one your gateway exposes, at a cadence that resolves the trend. If it is not in the feed you already receive, it is a hardware project, not a software one.
A warning that arrives ninety minutes before failure is an alert, not a maintenance plan. You need enough interval to get the unit to a bay and the part on a shelf.
If the component is cheap, quick to change and fails without taking anything else with it, run it to failure and spend the attention elsewhere. That is a legitimate strategy, not a concession.
A Pilot With Kill Criteria
The reason most predictive pilots neither succeed nor fail is that nobody wrote down in advance what success would look like. Fill this in before anything is installed.
One or two components, from the four-gate shortlist. Not a platform, not a fleet-wide rollout, not "all fault codes".
A monitored group and a matched control group you deliberately do not monitor. Without the control you will credit the programme for a mild winter.
At least three P-F intervals for the chosen component, so the window has a fair chance to be exercised more than once.
Half the estimated P-F interval, reduced further if detection confidence is low or the consequence is safety-critical.
Named part numbers held or on a committed lead time shorter than the net P-F interval. Otherwise the pilot tests your purchasing, not your prediction.
Written as numbers before the start: confirmed rate, median lead time achieved, and unplanned events against the control group.
The conditions under which you stop. For example: confirmed rate below a stated floor after two intervals, or a missed failure in the monitored group with no prior alert. Agreeing this in advance is what makes the pilot honest.
One named person in the shop, not a committee and not the vendor.
The Seven Numbers That Tell You Whether It Worked
Note that none of them is "alerts generated". Swipe the table on mobile.
| Measure | How to compute it | What it tells you |
|---|---|---|
| Lead time actually achieved | Median days between the first alert and the work order being closed | If it is under a week you are not predicting, you are reacting slightly earlier |
| Alerts per unit per month | Total raised, split into acted on, watched, and dismissed | A dismissal rate above roughly a third means the threshold is wrong, not the fleet |
| Confirmed rate | Share of alerts where the inspection found the predicted condition | This is the only number that tells you whether the signal is real |
| Missed failures | Failures in the monitored population that produced no prior alert | The uncomfortable metric, and the one that decides whether to expand the pilot |
| Unplanned events in the monitored group | Compared against a matched group you did not monitor | Without the control group you cannot separate your programme from a mild winter |
| Parts availability at the moment of the alert | Share of alerts where the part was on hand | Prediction without stocking just changes who waits |
| Technician trust | Do they inspect on an alert without being chased? | A programme the shop does not believe is a reporting exercise |
Keep the alert, the inspection finding and the closed job on one record — the inspection report and the preventive maintenance schedule against the same unit — because the confirmed rate is uncomputable if the alert lives in one system and the finding in another. That linkage is also the labelled history a real prognostic model would need later.
Implementation Questions Maintenance Teams Ask
What is the P-F interval and why does it matter?
It is the time between the point a failure-in-the-making first becomes detectable and the point the component no longer meets its performance standard. It matters because it sets your monitoring frequency: conventional practice is to inspect or sample at one-half the interval, so that at least one check lands inside the window. A programme built without estimating it is monitoring on a schedule that has no relationship to the failure it is trying to catch. Book a pilot scoping call.
How do I estimate the P-F interval for a truck component?
From your own failure history first — how long before each failure did something observable change — then from the component maker's guidance, then from comparable published work. It will be a range rather than a number, and that is workable: take the short end. If you have no failure history with signal data attached, collecting that is the first phase of the programme rather than an obstacle to it. Open an account and start collecting.
What is the net P-F interval?
The detection window minus the time you need to act on what you found — diagnose, source the part, book the bay, release the unit. If your parts lead time is longer than the P-F interval, the alert cannot prevent the failure no matter how good the detection is. This is the single most common reason a technically successful pilot delivers nothing. Work it through with us.
Which truck components are worth monitoring?
Ones that degrade rather than fail suddenly, that emit a signal you already receive, whose P-F interval is long enough to act inside, and whose failure is expensive enough to justify the attention. That combination is narrower than it sounds. Components that fail randomly have no detectable onset, and no amount of data changes that. Try the screening on three units.
Why is age-based replacement considered ineffective?
Because most observed failures are not age-related. The United Airlines reliability studies identified six failure patterns, and only three show failure rate rising with age; for the majority, a component is no more likely to fail at 300,000 miles than at 100,000. Replacing on a calendar for those does not reduce failures, and by introducing new parts it can add infant-mortality failures. Review your own PM strategy with us.
Does this mean I should stop doing preventive maintenance?
No. Lubrication, filter changes, adjustments and inspections are not age-based component replacement — they are what keeps the degradation curve shallow in the first place. The finding argues against scheduled overhaul and replacement of components that show no age relationship, not against maintaining the vehicle. Keep both in one schedule free.
How long before a predictive programme pays back?
Longer than a vendor will tell you and shorter than doing nothing, and the honest answer depends on the P-F intervals of the components you chose. Design the pilot to run at least three intervals of the chosen component, measure against a control group, and judge on confirmed rate and lead time achieved rather than on alert volume. Set the measurement plan with us.
Start With Two Components and a Control Group
FleetRabbit keeps the signal, the alert, the inspection finding and the closed work order on one unit record, which is what makes a confirmed rate computable and a pilot conclusive. Bring your failure history to the session and we will estimate P-F intervals against it and write the charter with you.
No credit card required. Bring one component list and one year of failures.